This guide walks enterprise software architects, platform teams and data leaders through a pragmatic, step-by-step process for implementing an enterprise data fabric optimized for generative AI workloads in 2026. It focuses on concrete decisions you must make—architecture, integration patterns, scalability mechanisms, governance and how to measure ROI—so your enterprise solutions deliver reliable model inputs and controlled outputs at scale.
Why a data fabric for generative AI now?
Generative AI projects in large organizations place unique demands on data platforms: low-latency feature retrieval, high-volume vectorized representations, reproducible lineage for fine‑tuning or retrieval-augmented generation (RAG), and strict data governance. A data fabric—an architecture combining metadata, unified access, and pluggable processing—lets enterprises integrate heterogeneous data sources into AI-ready pipelines while preserving scalability, compliance and measurable ROI.
High-level architecture
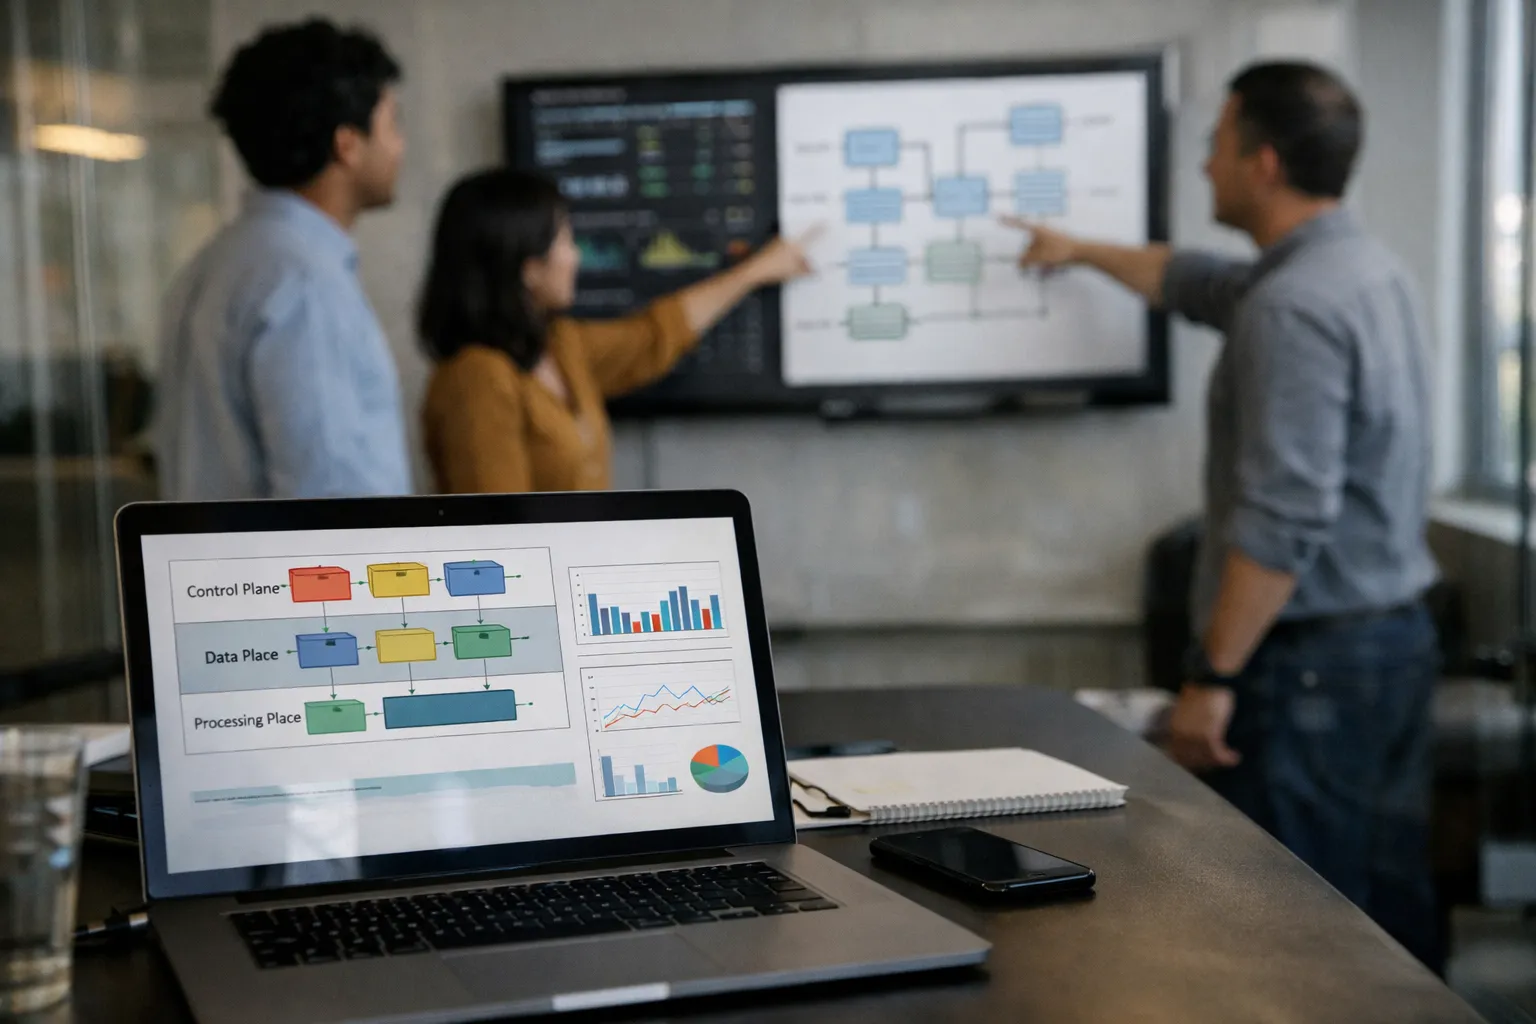
At a practical level, design your data fabric as three coordinated planes:
- Control plane (metadata & governance): central metadata catalog, schema registry, policy engine, lineage (OpenLineage or equivalent), access control, data contracts and audit trails.
- Data plane (storage & retrieval): object storage with table formats (Iceberg/Delta-style), hot caches for low-latency retrieval, and specialized stores for embeddings (vector stores or similarity engines).
- Processing plane (compute & orchestration): streaming/CDC ingestion, batch/ETL jobs, real-time feature serving, model inference endpoints and GPU provisioning—managed through Kubernetes + orchestration (Argo/airflow/etc.).
Integration across planes must be standardized via APIs, events and data contracts to preserve interoperability and enable progressive implementation.
Step-by-step implementation plan
Below is a phased plan you can implement over 6–12 months depending on scope. Adjust timelines for regulated industries or larger estates.
Phase 0 — Executive alignment and ROI scoping (2–4 weeks)
- Define business use cases for generative AI (e.g., automated reporting, knowledge assistants, contract drafting).
- Identify key data domains and owners (sales CRM, ERP, product catalogs, knowledge bases).
- Set ROI targets: time-to-insight reduction, automation-driven FTE savings, model accuracy uplift, or revenue-attributed gains.
- Establish success metrics and an initial cost envelope (cloud spend, infra, licensing, engineering hours).
Phase 1 — Assessment and blueprint (4–8 weeks)
- Inventory data sources, formats, SLAs and compliance requirements; map data owners and stewards.
- Choose core building blocks: object storage (S3/GCS/ADLS), table format (Iceberg/Delta), metadata/catalog (open or commercial), and orchestration tool.
- Create a target-state architecture diagram showing control/data/processing planes and integration touchpoints (APIs, CDC streams, batch jobs, feature store APIs).
- Define minimal viable governance (RBAC, PII redaction, lineage) and data contracts for each domain.
Phase 2 — Pilot (8–12 weeks)
- Select a single, high-value use case (e.g., customer support RAG for top 10 customers) and implement end-to-end flow.
- Ingest source data via CDC or batch; normalize into a canonical schema; store raw and curated layers in object storage using a table format.
- Implement metadata capture and lineage for all pipeline steps (use OpenLineage or vendor equivalent).
- Build embedding/representation pipelines: standardized preprocessing, batching, embedding generation, and storage in a vector-optimized store.
- Expose a feature/embedding serving API with SLAs and monitor accuracy and latency.
Phase 3 — Hardening and federation (8–16 weeks)
- Expand to additional domains, maintaining data contracts and adding federated connectors where internal systems retain control (federated catalog pointers vs full ingestion).
- Implement caching and tiered storage: hot store for low-latency access, warm index for analytics, cold archive for compliance.
- Introduce autoscaling policies for GPU/CPU clusters used for embedding and inference; implement cost-aware scheduling.
- Harden governance: role-based access, automated PII scanning, consent and retention controls, and periodic lineage audits.
Phase 4 — Scale & optimize (ongoing)
- Measure KPIs, iterate on performance, and optimize cost (query patterns, compaction, storage classes).
- Introduce multi-region replication if latency or disaster recovery requires it.
- Operationalize continuous validation for embeddings and concept drift detection for model inputs.
Integration patterns and best practices
Integrations are the differentiator between a brittle platform and a resilient enterprise solution. Use these patterns:
- Event-first ingestion: CDC + streaming (Kafka-style or cloud streaming) for near real-time state, with materialized views for downstream consumers.
- API façade for retrieval: a centralized API gateway exposing unified feature and embedding retrieval to model-serving layers, decoupling clients from backend changes.
- Side-by-side federation: when full ingestion isn't possible, keep pointers in the catalog and implement federated query connectors to source systems.
- Contract-driven integration: publish and enforce data contracts (schema, SLAs, quality metrics) and integrate contract validation into CI pipelines.
Scalability tactics
- Partitioning and bucketing: partition datasets by time, customer, or logical domain; bucket large tables to limit compaction costs.
- Tiered storage: store recent data in high-performance tiers, older data in cold tiers with lifecycle policies.
- Autoscaling compute: use node pools for CPU/IO and separate GPU pools for embedding/inference with preemptible or spot instances where feasible.
- Query acceleration: deploy caching layers (Redis, Memcached) and vector indexes with sharding strategies tuned to workload.
- Backpressure & graceful degradation: implement circuit breakers and fallbacks in model-serving APIs so non-critical requests can queue or return cached results under load.
Governance, compliance and reproducibility
Generative AI increases auditability requirements. Make these controls foundational:
- Lineage capture for every data transformation and embedding generation step (OpenLineage events stored in an immutable log).
- Automated PII detection and masking at ingestion; apply policy-based access controls afterwards.
- Versioned datasets and model artifacts; immutable snapshotting of training data sets used for fine-tuning or evaluation.
- Metadata tags to indicate permitted use cases, retention requirements and export controls for each dataset.
Measuring ROI: metrics to track
Translate platform work into business value with clear, measurable KPIs:
- Time-to-insight: average time from data availability to usable feature/embedding in production (target: reduce by 50% in pilot).
- Model performance delta: measurable increase in accuracy/relevance in downstream generative tasks attributable to the fabric (A/B testing).
- Operational cost per inference/embedding: track cloud spend and engineering hours per 1M inferences or embeddings.
- Automation impact: FTE hours reduced via automation (e.g., faster SLA responses, automated document drafting) converted to $ savings.
- Uptime and SLA compliance: percentage of retrieval calls meeting latency SLOs.
Build a simple ROI model: annualized business benefit (FTE savings + revenue uplift) minus annual platform TCO (infra + licenses + staffing) = net benefit and payback period.
Common risks and mitigation
- Data quality drift: implement data and embedding validators with alerts; maintain retraining pipelines.
- Vendor lock-in: prefer composable APIs and open standards for metadata and table formats; keep critical assets portable.
- Cost overruns: enforce budget constraints with autoscaling, quotas and cost-monitoring dashboards tied to teams.
- Security exposure: apply least-privilege access, network controls and encryption at rest/in transit; subject model outputs to policy checks for sensitive disclosures.
Operational checklist before going to production
- Catalog and lineage enabled for all pipeline stages.
- Data contracts defined for each domain and enforced via CI validation.
- Feature/embedding serving API with SLA and grace degradation implemented.
- Autoscaling policies and cost controls configured for compute clusters.
- PII and compliance rules tested and automated.
- Disaster recovery and multi-region replication strategy validated.
- Monitoring and alerting on data quality, model drift and infra costs in place.
Tooling and technology guidance (2026 lens)
Choose components with enterprise-grade support for scalability and integration. In 2026, the pragmatic approach is to combine open standards with targeted managed services where they accelerate time-to-value. Key considerations:
- Storage and formats: object storage (S3/GCS/ADLS) + table format that supports time travel and compaction.
- Metadata & lineage: OpenLineage-compatible stacks or commercial catalogs that expose APIs and federate across silos.
- Ingestion: CDC for transactional sources, event streaming for real-time pipelines, and managed batch ingestion for bulk transfers.
- Feature and embedding serving: lightweight, horizontally scalable APIs with integration into CI/CD for model and data artifact versioning.
- Model orchestration: MLOps frameworks that integrate with your data fabric for reproducibility and deployment automation.
Case example (concise)
A global insurer implemented a data fabric to power an agent-assist generative AI. They piloted with claims data, using CDC to feed a canonical claims table, generated embeddings in nightly batches and exposed a low-latency API for RAG. Over 9 months they reduced agent average handling time by 22%, automated 18% of routine claim responses, and achieved a projected payback in 14 months due to reduced cycle time and fewer escalations.
Final recommendations
Start narrow, prove measurable value, and expand. Treat the data fabric as an evolving enterprise solution: prioritize integration contracts, metadata/lineage, and performance SLAs early. By aligning pilots with clear ROI targets and implementing scalable, standards-based building blocks, you can turn fragmented data into reliable, governed inputs for generative AI with predictable costs and demonstrable business impact.
If you need a concise project checklist or an ROI template tailored to your organization’s use case, I can provide one you can plug into executive planning sessions.