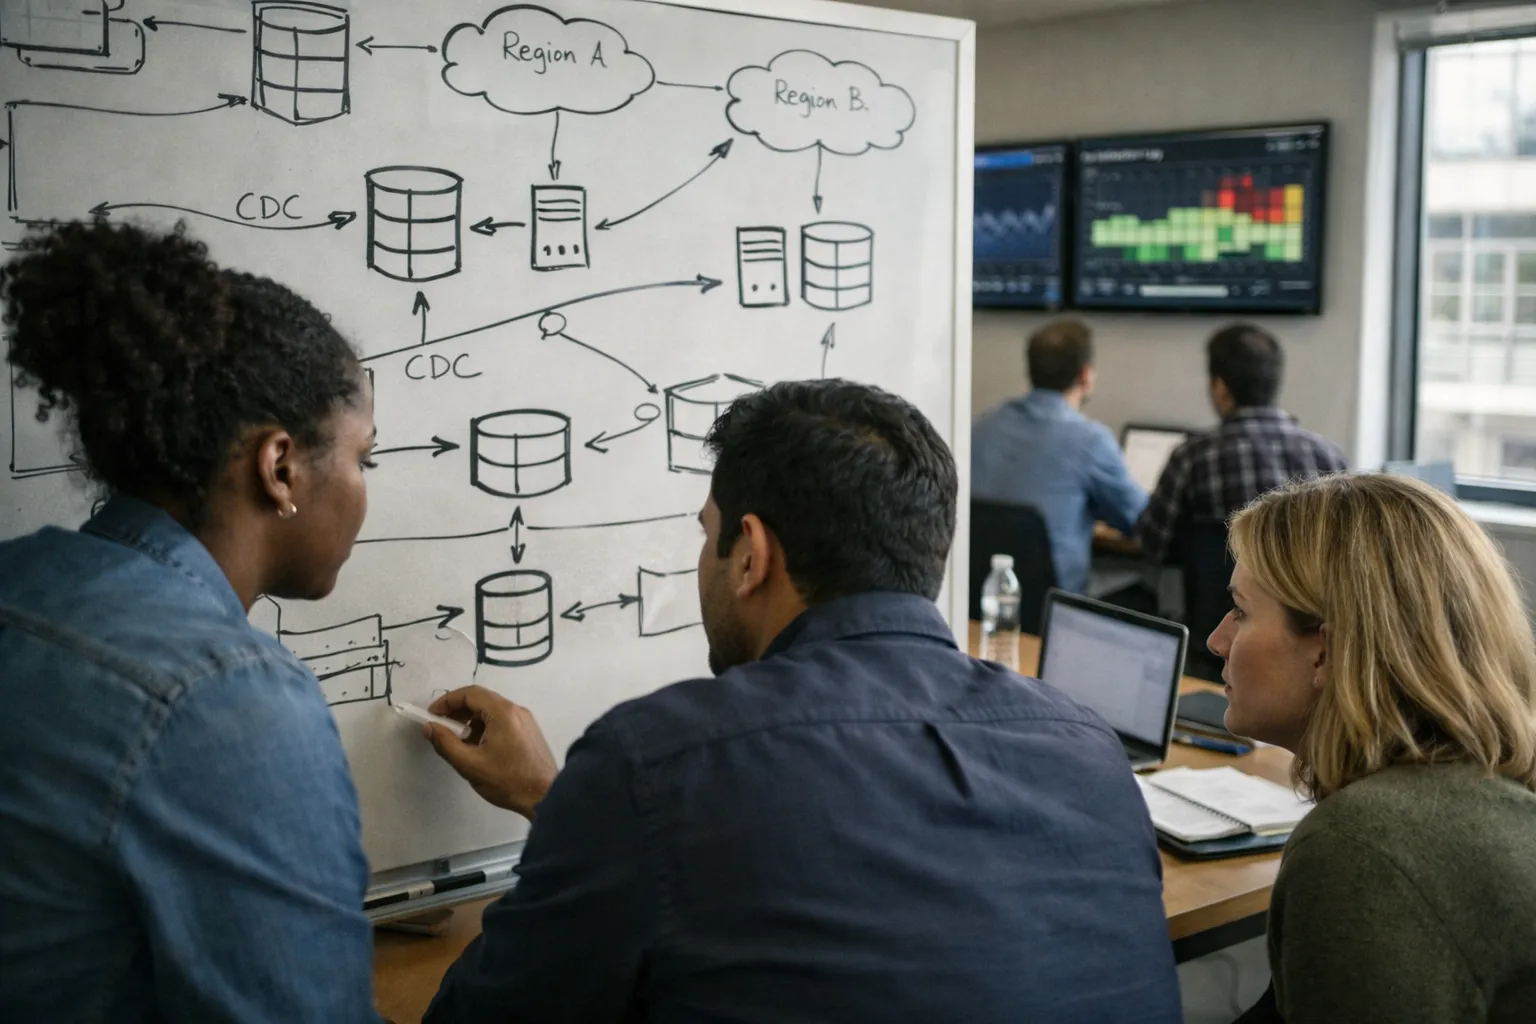
Enterprises running SaaS or global internal platforms increasingly require multi-region data synchronization to meet latency SLAs, local compliance, and availability targets. This guide walks technical leaders and architects through a concrete, actionable implementation plan for multi-region data sync using Change Data Capture (CDC) and event streaming, with emphasis on integration, scalability, conflict resolution, and measuring ROI.
Why multi-region sync matters in 2026
Over the past three years the business drivers for multi-region deployments have intensified: stricter data residency and sovereignty requirements, rising customer expectations for sub-100ms local latency, and risk mitigation against region-level outages. For enterprise solutions, a robust multi-region data sync strategy becomes part of product differentiation and regulatory compliance.
But multi-region sync is not a binary choice. It’s a collection of architectural trade-offs: consistency vs latency, operational complexity vs resilience, and capital/operational cost vs business value. This guide helps teams choose and implement the right pattern and measure ROI.
High-level approaches: pick the right model
There are three commonly used multi-region approaches. Choose based on workload characteristics and integration needs.
- Active-passive (Primary-replica) — One writable region; others serve reads. Simpler to implement; lowers conflict risk. Good for transactional systems that can tolerate regional write routing.
- Active-active with partitioned writes (geo-partitioning) — Users in a region write to a local partition. Ideal when data can be partitioned by tenant, account, or geography.
- Active-active with global replication — All regions accept writes for the same keys; requires strong conflict resolution (CRDTs, application merge rules) or causal/consensus mechanisms for strict correctness.
How to choose
- Latency-sensitive reads + few write conflicts → active-passive or geo-partitioning.
- Many write sources across regions → active-active with well-defined conflict resolution or CRDTs.
- Regulatory constraints (data residency) → geo-partitioning or selective replication of subsets.
CDC vs API-sync vs Hybrid: transport and integration
Data transport determines integration complexity and scalability. The most pragmatic path for most enterprise solutions in 2026 is CDC-driven event streaming with selective API sync where necessary.
CDC (recommended for relational stores)
- Mechanism: read DB transaction logs (binlog, WAL, logical decoding) and emit change events.
- Tools: Debezium connectors (Postgres, MySQL, SQL Server), Confluent/Kafka Connect, Redpanda Kafka-compatible brokers, AWS DMS for migrations/replication.
- Pros: low application changes, near-real-time, scalable with Kafka-style brokers, robust for bulk/backfill.
- Cons: schema evolution handling required; some databases need extra configuration or licensing (e.g., Oracle GoldenGate).
API-sync
- Mechanism: application-level events push changes via REST/gRPC to sync services.
- Pros: explicit business intent, easier to apply domain-level conflict resolution.
- Cons: requires application changes; harder to capture out-of-band DB changes; scale considerations for high-volume.
Hybrid — CDC for baseline sync, API events for business-critical cross-region writes and compensating actions.
Conflict resolution patterns
Conflict resolution is the hardest part of active-active designs. Pick a pattern that matches your domain semantics.
- Last-write-wins (LWW) — Simple but risky for non-idempotent business operations.
- Application-level merge — Emit domain events with intent (e.g., "increase_balance +$X") and reconcile by replaying commands. Requires designing idempotent, commutative operations.
- CRDTs (convergent replicated data types) — Useful for counters, sets, some collaborative models; require careful model mapping.
- Version vectors / vector clocks — Detect concurrency and escalate to business logic or human review.
- Directed conflict resolution with authoritative source — Some domains allow one region to be authoritative per key (e.g., account home region).
Recommendation: for enterprise SaaS, prefer geo-partitioning where possible; when global writes are required, use intent-based events or CRDTs for commutative operations and version vectors for others.
Architecture blueprint — CDC + streaming (practical pattern)
Below is a practical architecture used by many enterprise solutions:
- Database write occurs in local region (Postgres/MySQL/SQL Server).
- CDC connector (Debezium or cloud DMS) reads WAL/binlog and converts to change events.
- Events published to a global event bus (Kafka/Redpanda/Confluent) with geo-replication / tiered storage.
- Region-local stream processors (Kafka Streams, ksqlDB, Materialize) apply business transformations, de-duplication, and conflict detection.
- Local region ingestion writes the materialized state to the region-local datastore and updates caches/CDNs.
- Observability & control plane monitors replication lag, conflict rate, throughput; admin UIs expose reconciliation workflows.
For regulated data, apply selective replication or tokenization at the stream processor to avoid exporting PII across jurisdictional boundaries.
Operational concerns and best practices
- Schema evolution: use Avro/Protobuf with schema registry (Confluent Schema Registry, Apicurio) to handle forward/backward compatibility.
- Backfill and bootstrap: plan for initial snapshot + CDC tailing; tools like Debezium and AWS DMS support snapshotting with minimal downtime.
- Idempotency: incorporate unique event IDs and deduplication at consumers to tolerate retries.
- Monitoring: track replication lag (seconds), consumer lag, conflict rate, error rate, P99 read latency, and throughput (events/sec). Make dashboards part of SLOs.
- Testing: chaos tests for region failover, conflict injection tests, and compliance audits for data residency.
- Security: encrypt events in transit and at rest, apply per-region access controls, and audit change events for traceability.
Implementation checklist — phased plan
Implement in stages to reduce risk and measure ROI at each step.
- Assess — Inventory data domains, write locality, compliance constraints, and current latency metrics. Label datasets as global, regional-only, or restricted.
- Prototype — Build a small CDC pipeline for a non-critical table using Debezium → Kafka → consumer in another region. Measure lag, throughput, and operational overhead.
- Define consistency model — For each data domain, decide active-passive, geo-partition, or active-active with conflict rules.
- Implement control plane — Schema registry, monitoring, alerting, and an admin reconciliation UI for conflicts.
- Rollout — Migrate workloads incrementally: read-only regional cache → partial reads + local writes for geo-partitioned tenants → full multi-region for chosen domains.
- Automate & harden — Add blue-green switching, automated failover playbooks, and runbooks for conflict resolution.
Measuring ROI — what to track
Quantify benefits to justify enterprise investment. Key metrics:
- Customer-facing latency improvements (median & P99) and correlated impact on conversion or retention.
- Compliance cost reduction — quantified savings by avoiding rehosting, fines, or manual data localization efforts.
- Availability improvement — measurable reduction in cross-region outage blast radius (MTTR, number of incidents).
- Operational cost — incremental costs for streaming infra (broker hours, storage, egress) vs savings from reduced cross-region API calls and caching.
- Time to market for region-specific features — faster launches in new markets enabled by the platform.
Example ROI calculation: if multi-region sync reduces perceived latency for a region by 150ms and increases conversion by 2%, multiply that revenue uplift by customer base in that region, subtract incremental infra and engineering cost amortized over 12 months to produce NPV and payback period.
Tooling and vendor considerations (2026)
Choose tools that reduce integration effort and scale predictably. Typical stacks in 2026:
- CDC connectors: Debezium (open source), cloud-native connectors (AWS DMS for migrations; managed CDC services from major cloud providers).
- Event broker: Kafka (self-managed or Confluent Cloud), Redpanda (single-binary Kafka API), or cloud-managed streaming services (MSK, Pub/Sub with connectors).
- Stream processing: Kafka Streams, ksqlDB, Materialize for continuous views, or Flink for complex event processing.
- Datastores: region-local OLTP databases (Aurora, Cloud SQL, CockroachDB with geo-partitioning, Spanner for global consistency where needed).
- Schema & governance: Schema Registry, data catalog (e.g., Amundsen), and access governance solutions integrated into the pipeline.
Vendor selection should be driven by integration ease with your existing enterprise solutions, SLA guarantees, and total cost of ownership.
Common pitfalls and how to avoid them
- Underestimating conflict complexity — Run conflict simulation early and include product owners in defining resolution rules.
- Neglecting schema evolution — Enforce schema registry usage and compatibility policies from day one.
- Over-replicating sensitive data — Apply selective replication and anonymization where regulations disallow cross-border transfer.
- Operationalizing too late — Don’t treat multi-region sync as a one-off project; build monitoring, alerts, and runbooks early.
Case example (concise)
A mid-size ERP SaaS vendor in 2025 moved from single-region writes to geo-partitioning using tenant home-region rules. They implemented Debezium → Confluent Cloud for CDC and Kafka Connectors to regional read stores. Results after 9 months: P99 read latency decreased by 60% in target regions, regional churn reduced by 1.8%, and regulatory time-to-market for a European deployment was cut from 6 months to 8 weeks — a clear ROI for the project.
Conclusion: practical next steps
Multi-region data sync is a strategic, measurable improvement for many enterprise solutions. Start with a narrow pilot using CDC-based streaming, choose partitioning or conflict patterns that match your business domain, and instrument ROI metrics before scaling. With the right mix of tooling and operational discipline you can deliver lower latency, improved reliability, and regulatory compliance while keeping integration and scalability under control.
Checklist to start this week:
- Inventory which datasets need cross-region replication and which can remain regional.
- Run a 2-week CDC proof-of-concept for a non-critical table using Debezium → Redpanda or Confluent Cloud.
- Define SLOs (P99 latency, replication lag) and observability dashboards.
- Draft conflict resolution policy for any domain with multi-region writes.
When implemented carefully, multi-region data synchronization becomes a foundational capability that increases product competitiveness, reduces regulatory friction, and delivers measurable ROI.