Introduction
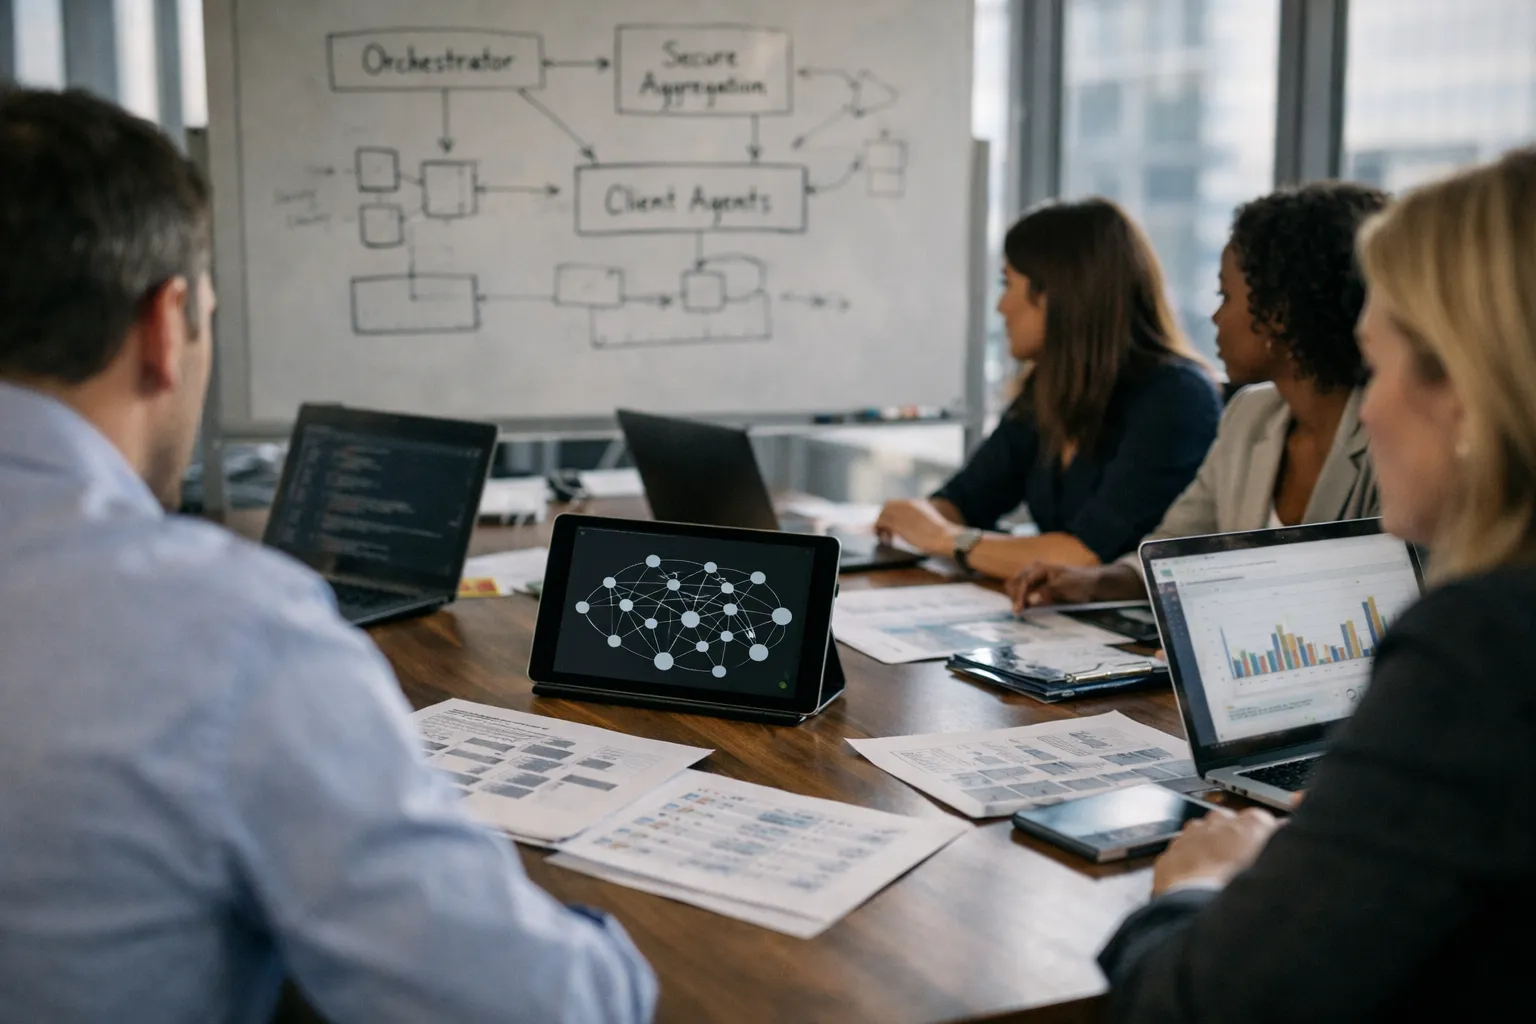
This guide explains how to design, implement and operate federated learning (FL) for cross‑company machine learning in July 2026. It’s written for AI‑for‑business teams, product managers and engineering leads who must obtain multi‑party model accuracy without centralizing personal data. You will find a step‑by‑step roadmap, updated tooling and privacy recommendations, real‑world examples from recent industry practice, and operational checklist items to move a pilot into production.
Prerequisites and context — what you should know first
Federated learning remains a targeted solution, not a universal replacement for data sharing. Use FL when: you cannot centralize personally identifiable information for regulatory, contractual or competitive reasons; improving generalization across diverse participants matters; and partners are willing to accept shared governance. Before starting, ensure:
- You have a clearly defined business objective and measurable success metrics (AUC lift, FPR @ fixed TPR, revenue or cost delta).
- Partner technical environments are documented (cloud provider, on‑prem, network egress constraints, CPU/GPU availability).
- There is an attainable legal baseline (DPA, model use rules, audit rights) and an executive sponsor for governance.
Why federated learning in 2026, and when it makes sense
Since 2024 FL has moved from research pilots into regulated, production use cases in finance, retail and telecom. Key drivers in 2026:
- Stronger regulatory focus on model governance and data minimization, prompting organizations to prefer collaborative training over raw data exchange.
- More mature open‑source and commercial stacks that reduce integration cost (managed FL services and orchestration templates are now common).
- Operational patterns—secure aggregation + DP + contribution accounting—have become standard practice for consortiums that need auditable outcomes.
Do not choose FL when: a central secure repository is legally acceptable and technically simpler; model requires raw, linked records across partners; or the scope is so narrow that FL operational overhead outweighs benefits.
High‑level checklist before you start
- Define objective, primary metric and minimum viable data schema.
- Map partner environments and minimal compute/network specs.
- Negotiate a baseline legal & governance framework (roles, IP rights, auditability).
- Select privacy baseline: secure aggregation, DP, TEEs or MPC/HE depending on risk tolerance.
- Pick an orchestration & observability stack compatible with partner clouds.
Step 1 — Define the use case, success metrics and minimum data schema
Start narrow with a one‑page problem statement and a signed minimal data contract. Example deliverables:
- Objective: reduce chargeback fraud by X% while maintaining false‑decline rate under Y%.
- Metrics: primary metric (AUC or precision@recall), secondary operational KPIs (round success rate, model rollout latency).
- Schema: 15–40 columns with canonical names, units and agreed categorical encodings. Use feature hashing or a shared vocabulary registry to avoid sharing raw mapping files.
Why: a narrowly scoped pilot reduces engineering and legal friction and produces measurable signals quickly.
Step 2 — Choose architecture & deployment pattern
Two dominant patterns remain in 2026:
- Central orchestrator (server‑client) — orchestration server collects encrypted/aggregated updates. Best for consortiums with a neutral hosting arrangement.
- Decentralized / peer‑to‑peer — used when any central coordinator is unacceptable. Operationally costly and rare in multi‑company settings.
Recommended: central orchestrator hosted by a neutral third party or consortium cloud account with transparent audit logs and hardware attestation.
Infrastructure choices (practical)
- Orchestrator: containerized service on Kubernetes with mutual TLS, key management (KMS) and signed artifact registries.
- Clients: containerized training jobs or lightweight agents scheduled in partner environments; support both CPU and GPU.\li>
- Comm: gRPC or HTTPS with mutual auth; rate limiting and observability endpoints for training health.
- Storage: local data stays in partner environments; orchestrator stores versioned model checkpoints, DP bookkeeping and signed logs.
Step 3 — Pick frameworks and privacy tech (2026 landscape)
By mid‑2026 the ecosystem offers several mature options. Choose based on stack and scale:
- Flower — flexible, framework‑agnostic and Kubernetes‑friendly; widely used for cross‑company pilots.
- NVIDIA FLARE — enterprise feature set for large deployments and efficient secure aggregation.
- FATE — production deployments in financial consortia; strong MPC features.
- Privacy libraries: Google DP (DP accounting), Opacus (PyTorch DP‑SGD), and Microsoft SEAL (HE) for teams integrating cryptography.
Operational toolchain: MLflow or Weights & Biases for experiment tracking, Prometheus/Grafana for observability, Argo/Kubernetes for orchestration. Managed FL offerings from cloud vendors now include templates that speed onboarding; vet them for closed‑source components before relying on them.
Step 4 — Design privacy & security controls
Adopt a layered approach:
- Secure aggregation — prevents the orchestrator from seeing individual updates; implement Bonawitz‑style protocols or vendor equivalents.
- Differential Privacy (DP) — DP‑SGD or per‑round noise with accounting. Typical business pilots tolerate epsilons in the low single digits after empirical tuning; track cumulative epsilon per participant.
- TEEs + hardware attestation — use where regulatory or contractual demands require an attested compute environment (Confidential Computing Consortium standards are widely adopted).
- MPC/HE — reserve for the smallest, highest‑sensitivity aggregates due to performance costs; consider hybrid designs (secure aggregation for routine rounds, MPC for verification rounds).
Why: defense‑in‑depth is the industry default in 2026. Combine secure aggregation with DP and signed, auditable logs to satisfy both legal teams and auditors.
Step 5 — Implement client‑side training and validation
Practical client requirements:
- Reproducible environment: signed container images and dependency pinning; publish SBOMs for inspection.
- Data validation: schema validation, unit checks and static feature drift tests executed before each round.
- Local training: run fixed epochs/steps, compute model deltas, and apply DP mechanisms locally if using local DP.
- Telemetry: send only DP‑protected or aggregated telemetry (per‑round loss, success/failure flags) to avoid leakage.
- Resource governance: enforce CPU/GPU, disk and network limits; implement timeouts to prevent slow or malicious clients from stalling rounds.
Why: reproducibility and strict client controls reduce both security and ops risk across multiple partners.
Step 6 — Aggregation, model updates and contribution accounting
Aggregation workflow:
- Collect encrypted updates; perform secure aggregation to compute the aggregate model delta.
- Optionally apply DP noise at the aggregator level and log epsilon consumption per partner.
- Register the new model version in a versioned registry and publish an auditable model‑change report.
- Compute contribution estimates (Shapley approximations, TracIn variants) to support incentive models and billing.
Why: transparent contribution accounting helps commercialize the effort and align incentives across participants.
Step 7 — Monitoring, validation and drift detection
Implement multi‑layer monitoring:
- Training health: per‑round success rate, client divergence, and failed client counts.
- Model quality: global validation using mirrored non‑sensitive test sets or synthetic holdouts agreed on at onboarding.
- Drift: histogram or quantile summaries of key features and predictions (DP‑protected) from each partner.
- Privacy budget: automated epsilon accounting with alerts when a partner approaches allocation limits.
Operational rule: automate rollbacks and maintain a runbook. If a global model degrades partner‑specific compliance or business KPIs, have a tested rollback within SLA.
Step 8 — Legal, governance and commercial arrangements
Key contract elements in 2026:
- Clear role definitions (controller/processor) per jurisdiction and DPA clauses covering FL operations.
- Model governance: ownership, derivative use, re‑distribution limits and certification processes for model snapshots.
- Auditability: signed model artifacts, cryptographic proofs of aggregation, and access to attestation reports for TEEs.
- Incentives & cost sharing: use contribution accounting to allocate infrastructure and operational costs; define commercial licensing or paid‑access tiers for high contributors.
Regulatory note: consider obligations under GDPR and similar regional laws; if your model falls into a regulated category (e.g., credit scoring, biometric risk), implement the higher governance standards required by regulators and document decisions vigorously.
Step 9 — Pilot timeline, KPIs and scaling plan
Suggested pilot phases and timing (pragmatic):
- Weeks 0–4: onboard partners, align schema, finalize legal templates.
- Weeks 4–8: build and test signed client images; run local unit tests and synthetic adversarial tests.
- Weeks 8–12: run first federated rounds with 3–6 partners; tune DP parameters and secure aggregation end‑to‑end.
- Months 3–6: expand partner base, harden monitoring, and roll a controlled production release.
KPIs to track: model utility vs best local baseline, round reliability, privacy budget consumption, partner adoption and business impact metrics (revenue or cost reductions attributable to the global model).
Costs, trade‑offs and common pitfalls
Costs to budget:
- Client compute and network costs; DP and HE increase compute.
- Orchestrator and attestation infrastructure; logging and long‑term storage of artifacts for audits.
- Legal and engineering time for schema alignment and governance.
Common pitfalls in 2026:
- Underestimating partner onboarding friction—signed images, SBOMs and attestation checks are often blocking items.
- Ignoring heterogeneity—clients with widely varying compute or data distributions can destabilize rounds unless adaptive client selection and reweighting are applied.
- Lack of contribution accounting—without transparent compensation rules, partners disengage as the program scales.
Real‑world example (concise)
Example: a regional payments network and five issuing banks piloted FL to improve fraud detection. They standardized a 30‑field transaction schema, used Flower with secure aggregation and DP‑SGD applied at the orchestrator. After 10 federated rounds the consortium measured a consistent lift versus each bank’s local model in cross‑partner fraud patterns. Contribution accounting drove a cost‑sharing agreement: two banks that supplied high‑volume, high‑value signals received earlier model snapshots in exchange for covering a larger share of infra costs.
Operational checklist before first production rollout
- Signed legal agreements and governance charter.
- Reproducible, signed client images with SBOMs and attestation flows.
- DP, secure aggregation and adversarial tests completed on synthetic data.
- Monitoring, rollback automation and runbooks in place.
- Commercial and contribution accounting terms agreed.
Pro tips (advanced)
- Use adaptive client selection and FedProx‑style regularization to handle system and statistical heterogeneity.
- Compress model updates (quantization, sparsification) to reduce bandwidth and speed up rounds—use error feedback to maintain accuracy.
- Run occasional “verification rounds” using MPC or attested TEEs to prove model integrity against poisoning without exposing raw data.
- Automate partner onboarding with a developer portal that provides signed images, schema validators and test datasets to reduce friction.
Common mistakes to avoid
- Starting without a signed minimal data contract—schema drift quickly kills pilots.
- Exposing per‑client unprotected telemetry that can be re‑identified.
- Assuming DP or secure aggregation alone is a silver bullet—use layered defenses and auditability.
Frequently asked questions
When is federated learning clearly the wrong choice?
If you can legally centralize and secure the raw data with lower cost and faster iteration, central training is usually simpler and more effective. Also avoid FL when the model requires tight per‑record joins across partners (linkage that cannot be approximated) or when partner data is too small or too heterogeneous to contribute reliable signal.
How should I choose DP parameters (epsilon) in practice?
There is no one‑size‑fits‑all epsilon. Start with empirical sweeps on representative synthetic data to measure utility loss, consult legal/compliance teams, and document the risk/benefit. In business pilots, teams commonly accept low single‑digit epsilons after testing; always track cumulative epsilon per partner and automate enforcement of budget limits.
Does secure aggregation eliminate the need for legal agreements?
No. Secure aggregation reduces operational risk by preventing the orchestrator from seeing raw updates, but contracts are still necessary to define roles, ownership, permissible model uses and audit rights. Cryptography complements but does not replace legal governance.
How do we defend against poisoned client updates?
Use a combination of defenses: anomaly detection on update norms, robust aggregation methods (median/trimmed mean), periodic attested verification rounds (MPC/TEE), and governance controls that require signed, audited client binaries and identity vetting of participants.
Can small partners participate without GPUs?
Yes. Design the protocol to accept heterogeneous clients: allow CPU‑only clients with smaller local epochs or fewer model parameters (personalized heads), or perform federated transfer learning where only a small set of parameters is trained at edge while a shared trunk remains fixed.
Resources and references
- Bonawitz et al., "Practical Secure Aggregation for Federated Learning" (protocol reference).
- Flower, NVIDIA FLARE, FATE and OpenMined projects (open‑source FL tooling).
- Google DP library and Opacus for DP accounting and DP‑SGD implementations.
- Microsoft SEAL and widely used HE libraries for cryptographic experiments.
Final note: in 2026 federated learning is a pragmatic option for cross‑company ML when paired with clear governance and a layered privacy strategy. Start small, instrument heavily, and use contribution accounting to align commercial incentives—those operational disciplines make the difference between a pilot and a sustainable consortium.