Overview
This update (July 2026) revisits the trade‑offs between freshness, cost and complexity for enterprise LLM indexing. Since our original analysis, vendors and open‑source projects have added features (tiered vector storage, per‑vector metadata/versioning, managed CDC connectors) that shift operational trade‑offs. At the same time, cheaper encoder runtimes, more predictable embedding SLAs from major providers, and growing regulatory scrutiny around provenance make the engineering and procurement choices more consequential. This article synthesizes those developments, provides updated decision rules and concrete operational controls you can use today.
Background: what changed since 2024–25
Three shifts matter for teams making indexing choices today:
- Vector platform maturity. Most major vector DB vendors and cloud providers now expose per‑vector last‑update timestamps, tombstones, and tiered hot/cold storage. That reduces some of the earlier workarounds for deletions and provenance.
- Embedding economics and runtime diversity. Quantized, CPU‑friendly encoders, and inexpensive on‑prem inference options allow many teams to move a large share of embedding work off vendor APIs—lowering variable cost and reducing API‑throttling risk during spikes.
- Operational best practices solidified. Engineering teams have standardized patterns—CDC‑to‑vector connectors, prioritized embedding queues, and observable freshness SLOs—so operational risk is now a controllable variable, not an intractable one.
Data & evidence: adoption trends and cost signals (2024–mid‑2026)
Quantitative industry reporting remains fragmented, but consolidated signals point to the following practical realities:
- Enterprise deployments commonly mix approaches: recent procurement briefs and vendor case studies show >60% of large deployments use a hybrid hot/cold pattern for knowledge bases and support systems.
- Embedding spend is no longer the dominant unknown for teams with in‑house inference. For organizations able to run encoders on inexpensive CPU instances or edge accelerators, embedding unit cost can drop by multiplex versus hosted API pricing—turning write I/O and storage into the larger marginal costs.
- Failure modes have been quantified: teams report that unbounded embedding backlogs during data migrations can multiply monthly bills by 2–5x if not rate limited. As a result, circuit breakers and prioritized queues are now typical in production pipelines.
These practical signals matter more than vendor promises: they show which costs you can control (embed locally, buffer writes) and which you must negotiate (vector DB write pricing, storage tiers, SLAs).
Three indexing approaches (revisited)
1) Periodic batch reindexing
Description: Rebuild or append to indices at fixed intervals (hourly, nightly, weekly). Modern batched pipelines often use CDC snapshots and incremental chunking rather than full re‑embeds.
Updated pros:
- Best predictability—especially when you rely on managed vector DBs with predictable storage billing.
- Works well with immutable snapshot provenance requirements (audit, compliance or legal review) because a batch process produces versioned snapshots.
- New tooling reduces full‑reindex cost: delta detection, chunk‑level checksums and embedding caches make incremental batches cheaper than in 2024.
Updated cons:
- Windowed staleness persists. For high‑risk domains (fraud alerts, active incident support), even hourly batches may be insufficient.
- Large delta bursts (bulk imports, migrations) still risk large compute spikes unless you rate limit or throttle embedding flows.
2) Streaming incremental updates
Description: CDC events, webhooks, or message bus events trigger per‑object embedding upserts and deletes.
Updated pros:
- Near real‑time freshness by design; necessary for incident response, active sales conversations, and billing‑sensitive support flows.
- With local quantized encoders, per‑update cost can be low—making streaming economically viable for many mid‑sized teams.
- When coupled with prioritized queues, streaming lets you define business‑critical routing (critical customer updates first).
Updated cons:
- Engineering complexity remains: idempotency, ordering, and correct tombstone semantics are non‑trivial even with vendor helper libraries.
- Operational volatility: sudden bursts still translate into variable compute/network demand unless you implement backpressure and bursting controls.
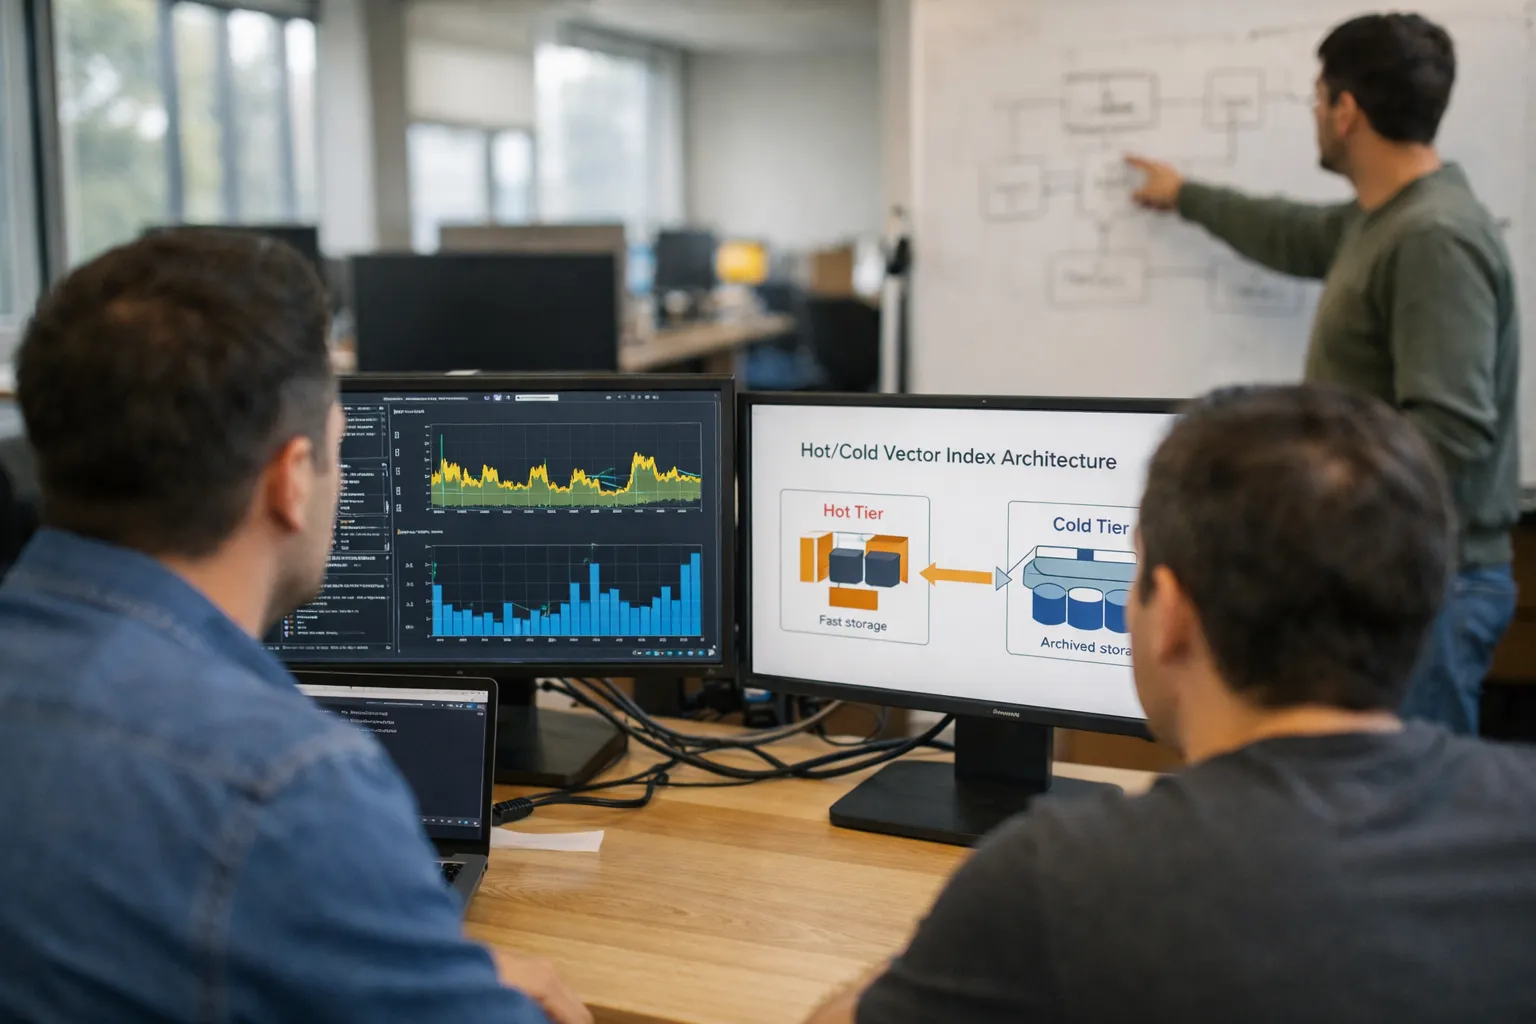
3) Hybrid hot/cold indexing
Description: Keep a small, frequently updated hot store for recent/critical content and a larger cold corpus refreshed with batch jobs. Query routing merges hot and cold results at runtime.
Updated pros:
- Most common production pattern in 2026—combines responsiveness for the working set with economical storage for the long tail.
- Vendor tiering and per‑vector TTLs reduce the amount of custom infrastructure teams must build.
Updated cons:
- Complexity in query scoring and de‑duplication remains the major integration cost; expect to invest in routing tests and A/B measurement.
- Latency penalties when queries probe both tiers are mitigated by asynchronous pre‑merging and cache warming techniques but require engineering investment.
Key trade‑offs: updated metrics & thresholds
Three practical metrics help procurement and engineering converge:
- Freshness latency (seconds/minutes/hours) — measured as the 95th percentile time from source change to vector readiness. Aim to build an SLO (e.g., 95% of critical document updates searchable within X minutes).
- Cost per effective update — total of embedding CPU/network cost, vector DB write cost, storage amortized per update, and query amplification when multiple indices are probed. Use end‑to‑end chargeback to compare approaches.
- Engineering risk and operational headroom — estimated team effort to implement idempotency, handle failures, and comply with regulations. Factor this into vendor selection and TCO calculations.
Rule‑of‑thumb thresholds (practical, not absolute): if your daily update volume exceeds ~0.1–0.5% of corpus size and updates are business‑sensitive, a streaming or hybrid hot store will likely be cost‑effective. If tolerated staleness is measured in days and change volume is low, batch remains the simplest choice.
Operational pitfall checklist (2026)
- Embedding backlogs and billing shocks: put hard quotas and circuit breakers on embedding queues; configure throttles for vendor APIs.
- Metadata drift and semantic correctness: treat metadata changes as first‑class events and store per‑vector provenance (origin, commit id, ingestion timestamp).
- Efficient deletions: confirm vendor tombstone and hard delete behavior and align that with retention policies and GDPR/CCPA obligations.
- Freshness observability: expose freshness SLOs and alerts (e.g., percentage of critical docs older than SLO threshold) and include them in runbook escalations.
Multiple perspectives
Engineering teams. Senior engineers we spoke with say the most valuable early investment is an embedding cache and an observable embedding queue—these universally reduced incidents and bill surprises.
Procurement and vendor view. Sales and procurement teams now prioritize vector DBs that publish per‑vector metrics (last update, storage tier, tombstone flags) and offer predictable write pricing or burst buffers in contracts.
Compliance and legal. Data‑protection teams prioritize immutable ingestion logs and per‑vector provenance so retrieval results can be audited; many enterprise contracts now include explicit requirements for deletion guarantees.
Updated decision framework
- Quantify the business cost of stale answers in the exact units your stakeholders care about (revenue at risk per hour of staleness, SLA penalties, compliance fines).
- Measure working set churn: instrument your sources to capture updates/day and percentage of corpus affected. If churn disproportionately affects a small working set, a hot/cold split is attractive.
- Run a pilot with measurable SLOs: implement a single streaming pipeline for a high‑value subset and compare cost, latency and operational effort to a batch baseline before rolling out.
Outlook — what to watch through 2027
- Standardization of vector metadata APIs. Expect cross‑vendor standards for per‑vector provenance and tombstone logs to make migrations and audits easier.
- More embedding offload to edge and on‑prem. As quantized encoders improve, the marginal cost advantage of using hosted embedding APIs will shrink for enterprises with stable workloads.
- Richer pricing models. Vendors are moving to explicit write‑IO and tiered storage pricing instead of opaque monthly bills—good for predictability but requiring contract diligence.
- Regulatory scrutiny. Expect regulators and auditors to ask for retrieval provenance and evidence of deletion procedures for AI systems used in regulated domains.
Practical checklist for teams ready to implement
- Define freshness SLOs tied to business outcomes (not vague minutes/hours).
- Run a two‑week pilot: measure 95p latency, embedding queue depth, and bill impact for streaming vs batch on a representative subset.
- Insist on per‑vector metadata and tombstone support in RFPs; validate with a POC that deletion semantics match compliance needs.
- Instrument for cost: track embedding CPU, write IOPS, storage, and query amplification in a single dashboard to support procurement conversations.
Conclusion
Freshness remains a business decision. Since 2024, product teams have gained better tools—tiered storage, per‑vector metadata, local encoders and mature CDC connectors—that make streaming and hybrid patterns practical for more organizations. But complexity and bill volatility have not disappeared; they are now manageable trade‑offs. Invest early in measurable SLOs, provenance metadata, and embedding queue controls. Use a measured pilot to decide between batch, streaming, and hybrid—because the right answer depends on your change rate, tolerance for staleness, and operational maturity.
FAQ
How should I measure "freshness" for indexing?
Measure the end‑to‑end time from a source change to a vector becoming searchable and include both mean and a percentile (95th or 99th). Tie that metric to business KPIs (e.g., percentage of critical customer issues answered with out‑of‑date info) and set SLOs and alerts based on those business‑facing thresholds.
Is hybrid always worth the extra complexity?
Not always. Hybrid is valuable when a small working set changes frequently but you must keep a large historical corpus searchable. If churn is uniformly low or staleness has minimal business impact, a batch strategy is simpler and cheaper. Pilot a hot store for a representative subset to validate the operational cost before committing system‑wide.
What operational controls reduce embedding‑bill surprises?
Use embedding queue quotas, circuit breakers, prioritized queues for critical updates, and an embedding cache. Where feasible, run encoders on owned infrastructure or use fixed‑cost inference to avoid API throttling and variable spend during spikes.
Do vector DBs reliably support deletes and versioning in 2026?
Most major providers now support tombstones, per‑vector last‑updated timestamps, and some versioning primitives—but the guarantees (soft vs hard delete timing, retention) vary. Validate deletion semantics in a POC and include those guarantees in contracts if you have regulatory requirements.
What's the single most important investment teams can make first?
Implement observable freshness SLOs and an embedding queue with throttles. Those two investments expose the true trade‑offs between batch, streaming, and hybrid in your environment and reduce both risk and surprise costs during rollouts.