Introduction — What you’ll learn and who this is for
This updated June 2026 guide shows product, ML engineering and platform teams how to run production-ready progressive rollouts for LLM-driven features. You’ll get a step‑by‑step process (feature flags, shadowing, canarying, staged expansion), specific telemetry and automation patterns, privacy/compliance controls, and operational examples that reflect practices and regulatory context current to mid‑2026. If you ship text or multimodal AI features in a product used by customers or employees, this is for you.
Prerequisites and context — what’s changed since early 2026
Since March 2026, three practical shifts shape rollout design:
- Operational governance expectations have hardened. Organizations are operationalizing the NIST AI Risk Management Framework and incorporating behavior specifications (model cards + behavioral contracts) into release criteria. Regulators and large enterprise buyers now expect demonstrable rollout controls for higher‑risk models.
- Model heterogeneity is the norm. Production stacks often mix hosted large models, distilled on‑prem models, and specialized micro‑models (safety, classification). This makes routing logic and cost planning more complex but allows cheaper shadow proxies for evaluation.
- Tooling has matured. Observability vendors and platform teams increasingly ship model-aware feature flags, token metering, and semantic diff tooling as first‑class components. Shadow pipelines and in‑flight model comparison are more automated than two years ago.
Assumptions before you begin:
- Your application has a model‑agnostic API gateway or sidecar capable of routing and mirroring requests.
- You can instrument requests with privacy‑preserving metadata (hashes, cohort ids) and set retention/consent policies per tenant.
- Your team can run short (minutes-to-days) human review rounds and has on‑call playbooks for automated rollback.
Why LLM rollouts need a different playbook
- Non-deterministic outputs: Quality variance and subtle semantic regressions are common; user behavioral metrics are often lagging indicators.
- Per-request cost & latency: Token and compute costs vary by prompt and model; rollouts can produce immediate spend spikes.
- Data sensitivity & compliance: Prompts frequently contain PII or business secrets; privacy and data residency requirements are now contractually enforced in many enterprise agreements.
- Stateful dependencies: Retrieval contexts, tool calls and external APIs introduce cascading failure modes that traditional feature rollouts do not surface.
Core principles for safe LLM progressive rollouts (updated)
- Minimize blast radius with model-aware cohorts: Use tenant, session and behavioral cohorts (e.g., new users only) to control exposure.
- Measure the right signals early: Safety triggers, hallucination estimates, calibrated confidence, token usage, and semantic divergence matter more than short‑term conversion for initial stages.
- Automate rollback and remediation: Use hard and soft rollback thresholds tied to both short windows (1–5m) and daily aggregates; include automated flag flips and throttles.
- Preserve privacy by design: Apply redaction, salted hashing, and tenant opt‑outs for shadowing. For regulated tenants, prefer local evaluation or federated shadow pipelines.
- Model contract & behavior specs: Require a behavior spec and model card for each candidate model that defines expected inputs, dangerous behaviors, and acceptable divergence bounds.
- Cost-aware experimentation: Use distilled proxies, token caps, and budget alarms to avoid runaway billing.
Architecture components (practical in 2026)
Updated architecture components and why they matter:
- Model-aware feature flagging: Flag systems that understand model identity and token budgets (either via vendor support or an internal layer) let you gate by model id and budget cap.
- Traffic router / policy proxy: An API gateway or sidecar with routing, mirroring, throttling and metadata enrichment (flag version, cohort id, prompt hash). Prefer policy engines that can execute runtime rules for token caps and region constraints.
- Shadow & synthetic evaluation pipeline: Mirrored pipeline that can route to a cheaper distilled model for bulk evaluation and to the candidate full model for sampling. Automation should run semantic diffs and safety checks asynchronously.
- Observability & model evaluation: Telemetry stack plus a model evaluation workspace (embedding comparisons, hallucination scorers, sampled human labeling). Instrument both signal metrics and human feedback loops.
- Governance & runbook automation: CI/CD steps to validate behavior specs, automated remediation jobs to flip flags, and a post‑incident audit trail storing salted hashes and aggregated evidence for compliance.
Step-by-step rollout process
Below is a repeatable sequence you can adopt and adapt; each step explains why it matters.
1. Define feature surface, behavior spec and metrics
- Document exactly what changes: prompt design, model swap, retrieval tuning, tool integration, or UI change. (Why: scope determines risk vectors.)
- Produce a short behavior spec: expected inputs, example safe outputs, known failure modes, unacceptable outputs, and a rollout stop criteria. (Why: provides an objective release gate.)
- Choose guardrail and business metrics:
- Safety & correctness: safety rule triggers per 1k responses, hallucination classifier score, calibrated confidence distribution
- Operational: p50/p95 latency, error rate, tokens/input and tokens/output
- Cost: projected delta cost per 1k requests and daily budget threshold
- Business: task completion rate, retention signals, or conversion—measured with a minimum exposure window before using for rollout decisions
- Set SLOs and automated thresholds for soft/hard rollback (example: hallucination classifier > 1.5% on a 24h rolling window or token spend +40% for 30 minutes triggers soft throttle; repetitive breaches trigger hard rollback).
2. Prepare safe testbeds: synthetic tests + internal canaries
- Build a synthetic corpus that includes adversarial prompts, privacy-sensitive prompts, and typical business queries. Include prompts that historically cause the product to fail.
- Run offline diffs: semantic similarity (embedding cosine thresholds), safety classifier outputs, response length and token estimates. (Why: removes early surprises and quantifies divergence.)
- Internal canaries: deploy to employees and trusted partners with clear reporting channels. Keep exposure small (1–2% of internal traffic) and run continuous human review of top divergence cases.
3. Implement feature flags and routing
- Create flags scoped by tenant, cohort, region, and session. Use versioned flags so you can roll forward to a new candidate without losing traceability.
- Implement routing logic that:
- Defaults to control model
- Routes flagged traffic to candidate
- Supports shadowing and sampled full‑model evaluation
- Attach privacy-preserving metadata to requests (salted prompt hash, cohort id, model id). Avoid logging raw prompts except for explicit, consented human review sessions.
4. Shadow traffic and cheaper proxies
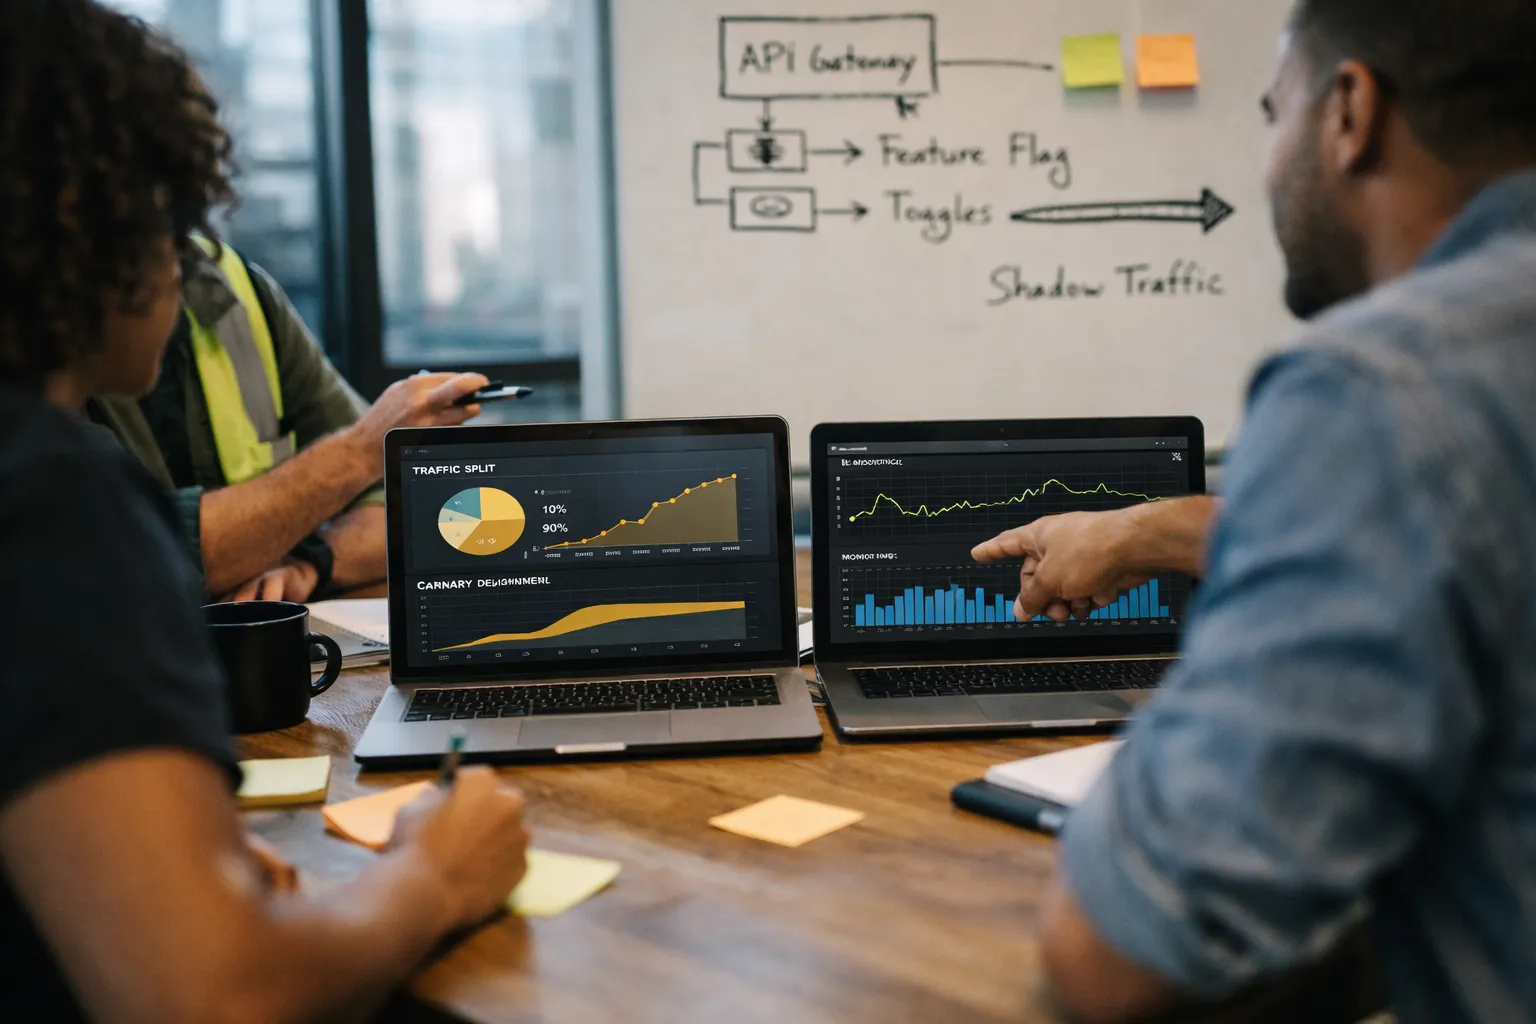
Shadowing in 2026 is more nuanced: copy production traffic to both a full candidate model and to a distilled (cheaper) proxy.
- Mirror 100% (or a sampled subset) of production requests to the candidate pipeline asynchronously.
- First pass: run the request through a distilled proxy to estimate semantic divergence and token impact at low cost.
- Second pass (sampled): run the candidate full model for safety scoring and human review. Prioritize requests that the proxy signals as divergent.
- Automate alerts for safety rule matches or high semantic divergence. Keep daily review cycles for top discrepancies.
5. Canarying — small, controlled exposure
- Start with a small external cohort (0.5–2% of live traffic) and prefer low‑risk tenants or sessions (read‑only workflows, preview flags).
- Use session affinity: assign a user to the same model for the session lifetime to avoid confusing alternating outputs.
- Grow exposure adaptively: double only after stability windows (e.g., 6–24 hours) and after no meaningful safety/quality regressions.
6. Scale and staged expansion
- Expand by tenant class and geography rather than pure percentage. Move non-critical or test tenants first; wait to flip large commercial accounts.
- Run parallel A/B tests for long‑horizon business metrics only once safety and semantic signals are stable; avoid making product decisions based on early canary samples alone.
- For full model replacements, plan blue/green deployments at the model level—keep the old pipeline warm for instant rollback.
Key metrics and instrumentation (concrete)
Design telemetry that captures both signal and context:
- Request metadata: model id/version, cohort id, hashed prompt id, tenant id (hashed if required), region
- Performance: p50/p95 latency, model queue time, backpressure and retry counts
- Cost: input/output tokens, estimated cost per request, daily cohort spend
- Quality & safety: hallucination classifier scores, safety rule matches, content policy flags, human rating samples
- Explainability & confidence: calibrated confidence scores, when available, and containment metrics for tool calls (API success/failure)
Instrument sampled full plaintext traces only under explicit consent and with retention policies. Prefer hashed or redacted storage for traces used in audits.
Automation, rollback and post-incident
- Soft rollback: Auto‑throttle exposure by percentage or route to the distilled proxy if a threshold breaches.
- Hard rollback: Flip feature flag to control for all cohorts; keep the previous model warm to avoid cold starts.
- Automated remediation job should:
- Evaluate metric windows (1m, 5m, 30m, 24h)
- Run semantic diffs on the last Nk requests and escalate high‑risk cases
- Flip flags, create incident records, and notify stakeholders when thresholds cross
- After any rollback, run a mandatory postmortem that includes behavior‑spec compliance, semantic diff statistics, and financial impact estimates.
Privacy, compliance and logging best practices (mid‑2026)
- Redaction-first: Remove PII before logs. Store salted hashes to enable duplication detection and auditing without raw data retention.
- Tenant governance: Allow tenants to opt out of shadowing or require on‑prem evaluation for regulated data. Respect data residency rules by routing evaluation traffic to the appropriate region.
- Consent & contracts: Update privacy policies and SLA language to cover progressive rollouts and shadowing where applicable.
- Audit trail: Maintain immutable records of feature flag changes, behavior specs used, and automated remediation actions for compliance audits.
Cost controls and practical savings tactics
- Budget alarms tied to cohort and model id; use cloud billing APIs and internal metering to trigger throttles.
- Prefer distilled or quantized proxy models for bulk shadowing and only run full candidate models on sampled requests flagged as high‑value or high‑divergence.
- Token caps per request and per session can bound runaway costs; combine caps with graceful degradation UX (e.g., “short answer mode”).
Testing & validation playbook
- Unit test prompt templates and input sanitation.
- Fuzz for prompt injection and adversarial content using automated red teams and synthetic adversarial generators.
- Integration tests for retrieval, tool calls and downstream APIs using synthetic datasets that mimic tenant constraints.
- Continuously schedule model diffs and human labeling for blind samples from shadowed traffic; prioritize high‑impact discrepancies for immediate review.
Example phased timeline (practical, condensed)
- Week 0: Behavior spec, synthetic tests and offline diffs against distilled proxy.
- Week 1–2: Shadowing to proxy + sampled full model runs; daily divergence scoring and top‑200 human reviews.
- Week 3: Internal canary (employees + beta tenants) 1–2%—monitor 24/7 with rollback automation active.
- Week 4–6: External canary expansion to 5–15% by tenant type and region; validate business KPIs after safety windows.
- Week 7+: Gradual full rollout with blue/green readiness and prolonged monitoring for slow‑moving business metrics.
Common mistakes and how to avoid them
- Too coarse flags: Avoid single binary flags; use versioned and cohort flags to isolate failures.
- Logging raw prompts by default: Redact and hash; only store plaintext for declared, consented human review sessions.
- Ignoring cost signals: Meter tokens early and use proxies for bulk shadowing to avoid surprise bills.
- Slow human feedback: Prioritize rapid review for top divergent cases and automate triage to reduce latency in remediation.
Pro tips
- Maintain a small library of “stress prompts” derived from production shadowing; run them automatically on every candidate model.
- Instrument a “confidence delta” metric — large negative deltas can indicate meaningful behavioral change even before human complaints.
- Use session affinity and model pinning for stateful features so users don’t receive inconsistent outputs mid‑session.
- Keep the previous model warm (blue/green) to avoid slow rollbacks due to cold‑start latencies on large models.
Closing checklist
- Behavior spec & model card created and validated
- Feature flags implemented and tested at cohort/session granularity
- Shadow pipeline operational with distilled proxies for cost-efficient evaluation
- Clear metric set, calibrated thresholds, and automated rollback configured
- Privacy-preserving logging, tenant opt-out, and regional routing in place
- Budget alarms, token caps, and runbooks prepared
Why this matters now
By mid‑2026, enterprises are being held to higher expectations for operational controls, transparency and data protection when shipping LLM features. Progressive rollouts — feature flags, shadowing and canarying — are not optional engineering niceties. They are the operational primitives that let teams iterate on capabilities while meeting contractual, financial and safety obligations. Apply the process above: start small, measure the right signals, automate rollback, protect user data, and let evidence drive expansion.
FAQ
How much traffic should I shadow vs. canary?
Shadowing can be broad (sample or full mirror) because it does not affect user responses; use a distilled proxy to reduce cost. Canarying should start tiny (0.5–2% of live traffic) and expand by cohort. Favor tenant/region staging over blind global percentage increases.
When should I use a distilled proxy instead of the full model for shadowing?
Use a distilled proxy for high‑volume shadowing to estimate semantic divergence and token impact cheaply. Reserve the full candidate for sampled requests flagged as high‑value or high‑divergence to verify safety and nuanced behavior.
What are reliable early indicators of a rollout problem?
Early indicators include spikes in safety rule triggers, a rising hallucination classifier score, a sudden increase in tokens per response, or a significant drop in calibrated confidence. These often appear before business metrics like conversion or retention move.
How do I retain privacy while allowing human review?
Default to redaction and salted hashing of prompts. Provide an opt‑in path for plaintext review, logged with consent and strict retention windows. For regulated tenants, offer on‑prem or regional evaluation so raw data never leaves their controlled environment.
Can I automate rollback entirely?
Yes—combine soft throttles and hard flag flips driven by short- and medium‑window thresholds. However, ensure a human on‑call reviews automated rollbacks for potential false positives and follows a documented postmortem process.