By Alex Rivera — Technology Editor
Overview: What we’re analyzing and why it matters
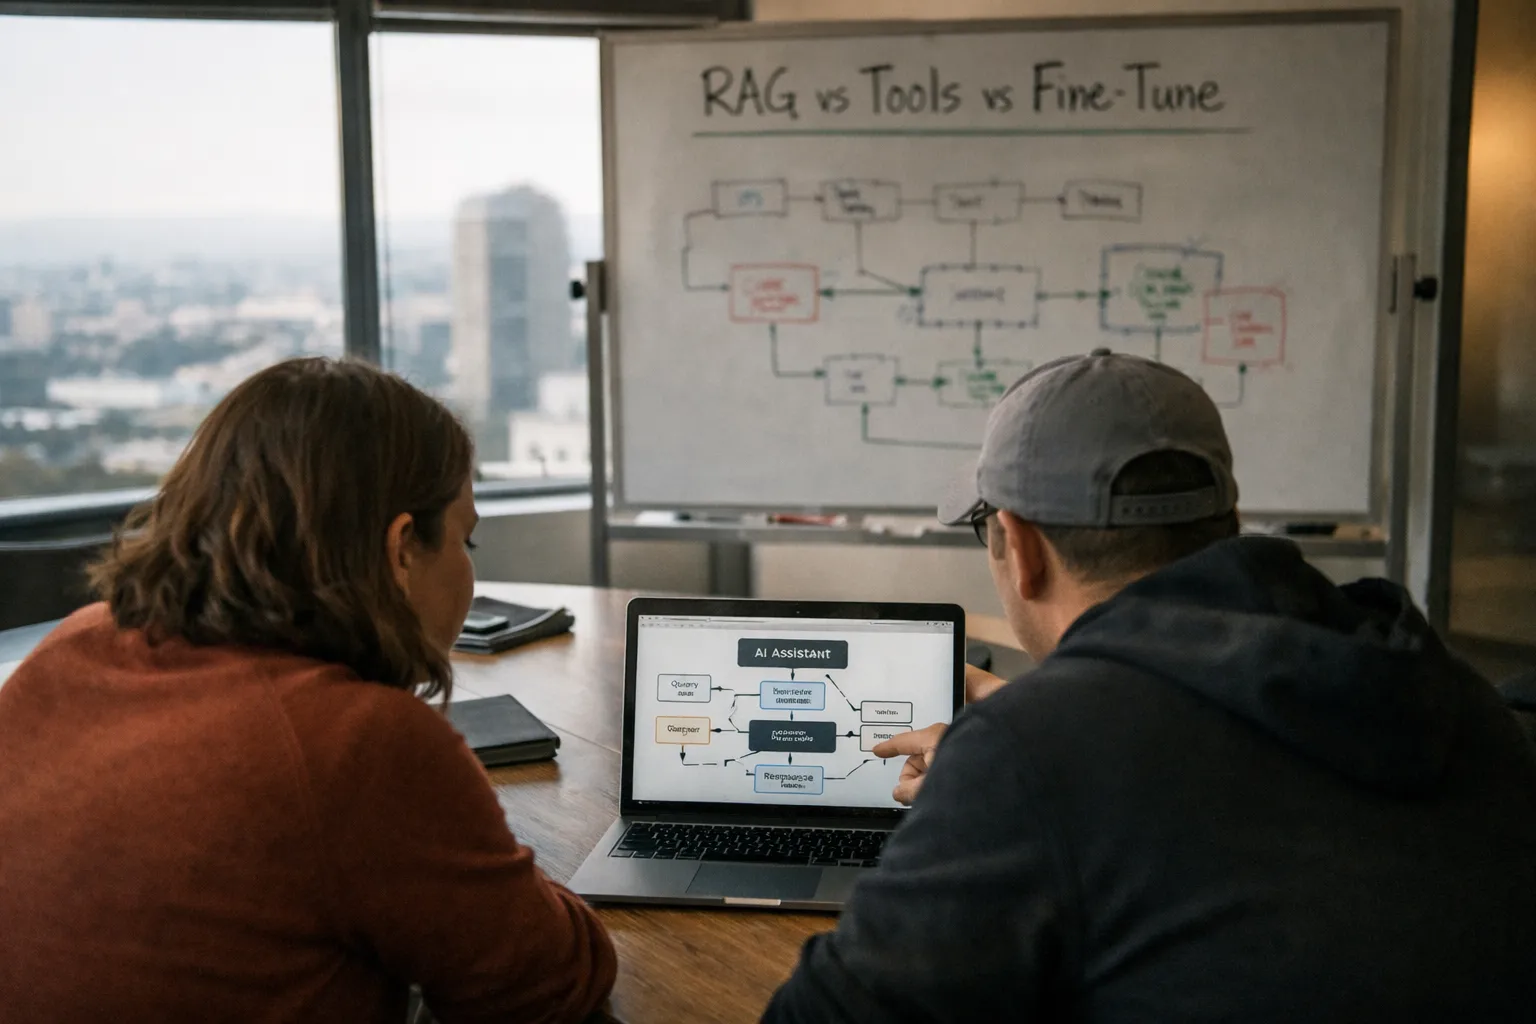
Three architectural choices still dominate how SaaS products add useful, safe AI features: retrieval-augmented generation (RAG), fine-tuning, and MCP-style tool calling (standardized connectors). Since January 2026 the discussion has shifted from “is AI useful?” to “how do we make it auditable, cost-predictable, and safely actionable?” This June 2026 update synthesizes what production teams are actually doing now, surface-level vendor moves worth noting, and concrete operational practices you can put into production this quarter.
Background: How we got here (brief)
Between 2023 and 2025, lots of SaaS AI features were thin model wrappers: send text, get text back. That quickly failed for real-world needs—customers demanded sources, current facts, and the ability for AI to act against systems (update a CRM record, open a ticket). In response three patterns hardened:
- RAG (Retrieval-Augmented Generation) — anchor responses in documents and return provenance.
- Fine-tuning — change a model’s behaviour by training on domain-specific examples.
- MCP-style tool calling — standardized, schema-driven connectors that let models discover and call actions safely (MCP = Model Context Protocol from Anthropic).
By mid-2026 most mature SaaS vendors assemble these patterns into hybrids: RAG for truth, selective fine-tuning for deterministic outputs, and connector layers for operations. The remaining challenge is not the model itself but the plumbing—access control, observability, and predictable costs.
Data and evidence: What’s measurable in production
RAG’s pragmatic ledger
RAG remains the default for document-driven knowledge use cases because it separates two problems: retrieval (what documents are relevant) and generation (how the model crafts an answer). That separation makes root-cause analysis tractable. In practice, production teams measure three signals continuously:
- Retrieval recall/precision against an authoritative test set (are we finding the right passages?)
- Generation fidelity to retrieved passages (does the model preserve facts or hallucinate?)
- Provenance completeness (is every assertion backed by a retrieval ID and a freshness timestamp?)
Operational best practices that matter: hybrid search (keyword + vector), tenant-scoped indices, chunking tuned to your domain’s context window, and freshness pipelines that surface recently changed documents to retrievers within minutes.
Fine-tuning’s narrower, higher-value role
Fine-tuning is now operationalized as a discipline rather than a silver bullet. Teams use it for:
- Enforcing strict output formats (JSON schemas, CSV rows) for downstream systems.
- Improving classification on company-specific taxonomies where labeled data is stable.
- Embedding brand and compliance constraints into generation style.
Safe practices that have gained traction in 2026: training with differential-privacy libraries, using synthetic augmentation to expand small datasets, and maintaining immutable model-version manifests so you can roll back a tuned model to a known good state.
Connector / MCP-style tool calling: action with guardrails
Tool calling moved from demonstrations to production, particularly in support automation, provisioning flows, and CRM updates. But action is riskier than answering: wrong writes are visible, auditable, and legally sensitive. That’s why MCP-style connectors—standardized schemas, argument validation, and explicit policy gates—are now considered basic hygiene.
Production teams measure connector safety by tracking: argument validation failure rate, percentage of actions intercepted by human-in-the-loop approvals, and incidence of scoped-token errors. A good connector system treats the model as a planner and the connector as a hardened, logged executor.
Multiple perspectives: What stakeholders care about now
Product leaders
Short-term product wins come from RAG-powered search, contextual help, and "preview-and-act" connectors that let users confirm an action before the agent executes. The KPI conversation has shifted from engagement to productivity—are users saving time and reducing error rates?
Engineers
Engineering teams now own continuous evaluation: automated recall/precision tests for retrievers, schema validation suites for tool calls, and regression checks for fine-tuned models. Tool-calling adds distributed-systems concerns—idempotency, retries, and durable human-approval queues.
Security, legal, and procurement
Procurement is demanding documented test results: provenance logs, tool-call audit trails, and contractual limitations on using customer data for vendor model training. The EU’s AI Act (now entering compliance phases for higher-risk systems) and sectoral guidance in finance and healthcare mean buyers must show how AI outputs are traceable and contestable.
Implications: How to choose and operate each approach
Decision guidance — who is it for?
- RAG — the librarian: Use when knowledge changes frequently. Ideal for product docs, contracts, and user-facing help centers.
- Fine-tuning — the translator: Use when outputs must be deterministic (strict JSON, billing adjustments, canonical tagging). Reserve it for stable schemas and controlled data sets.
- MCP-style tool calling — the operator: Use when AI must take actions across systems. Always pair with policy controls, preview UX, and auditable execution paths.
Operational checklist — what to implement this quarter
- Provenance-first logging: store retrieval IDs, exact prompt sent to the model, function-call arguments, connector responses, and pre/post snapshots for any write.
- Tenant-aware retrieval & entitlements: enforce tenant scoping at index time and at query time; run red-team scenarios that mix tenants’ data to find leaks.
- Dry-run and canary modes: deploy tool-calling agents in preview-only mode by default; require explicit, logged confirmation for high-risk actions.
- Continuous evaluation pipelines: add automatic skew detection for embeddings, hallucination regression tests, and schema-validation gates into CI/CD.
- Cost governance: cap per-request model budgets, monitor vector-search spend, and surface cost-per-response in your internal dashboards.
- Training hygiene: minimize PII in training data, use synthetic augmentation when possible, and run extraction tests to ensure no training-example leakage.
- Access & token lifecycle: use short-lived, scoped tokens for connectors and centralize secrets with rotation and least-privilege policies.
New 2026 practices worth adopting
Three patterns I’m seeing move from “nice-to-have” to required in production:
- Continuous Retrieval Evaluation (CRE): automated daily tests that surface retrieval drift when new docs change indexing behavior.
- Model behavior manifests: machine-readable model cards that list training data categories, intended usage, and known failure modes—plumbed into procurement and audit tools.
- Preview-and-act UX: in-product previews that show the retrieved evidence and the exact connector call the AI intends to make—users confirm before the action executes.
Outlook: What to watch for the rest of 2026
- Connector marketplaces mature: expect curated connector catalogs with security metadata, policy templates, and prebuilt privacy affordances.
- Procurement hardens: RFPs will increasingly require hallucination test results, tool-call audit samples, and signed data-use commitments.
- Feature-level governance sells: vendors that surface controls (per-role allowlists, preview UX) in product will outrun those that compete on raw model choice.
- Observability becomes a customer-facing differentiator: clear audit trails, cost forecasting, and incident explainers will be asked for during demos.
Multiple viewpoints: tradeoffs summarized
- RAG = factual grounding, engineering cost for retrieval correctness and freshness.
- Fine-tuning = deterministic behavior and format control, requires quality labels and privacy-aware training.
- MCP-style connectors = useful automation, requires strict validation, audit, and human approval primitives.
FAQ
Is RAG a substitute for fine-tuning?
No. RAG is the right tool when you must reflect frequently changing, authoritative documents. Fine-tuning is still the right tool when you need deterministic outputs (strict schema compliance, specific classification labels, or brand voice enforcement). The common pattern in production is: retrieve evidence, then generate with tuned constraints or validate generated output against a schema.
Does MCP-style tool calling replace RAG?
No. MCP-style connectors are about action; RAG is about evidence. A reliable flow often uses RAG to present provenance to the user, then—after user confirmation or policy checks—invokes a connector to perform the action. Treat connectors as guarded executors, not as truth sources.
How do I reduce the risk of sensitive data leaking from fine-tuned models?
Follow data-minimization: remove PII before training, use synthetic data augmentation, and employ differential-privacy techniques. Add extraction tests (attempt to recover training examples) to your CI so you can detect leakage, and insist on contractual guarantees from vendors that customer data won’t be used to train public models without explicit consent.
What are practical step-up controls for tool-calling agents?
Require role-based allowlists, multi-step confirmations for destructive actions, scoped short-lived tokens per connector, immutable audit logs with pre/post snapshots, and export of audit events to SIEMs. Implement dry-run for new connectors and maintain an approvals queue with durable evidence for every change.
When should a SaaS buyer walk away from a vendor’s AI claims?
If a vendor cannot produce documented evaluation results (hallucination tests, permission checks, tool-call logs), refuses contractual commitments on training-use and retention, or lacks basic auditability (no provenance or logging for AI actions), treat their AI features as unproven rather than strategic. Ask for a live demo of the audit trail—not just a marketing PPT.
Closing: the practical takeaway
If you remember one thing: the model is only one part of the product. In 2026 the winning SaaS features are those that marry reliable retrieval, auditable connectors, and disciplined fine-tuning—wrapped with visible controls for security and procurement. Models commoditize; governance, observability, and predictable cost controls win customers.
Who this is for: product leads choosing default architectures, engineering teams building the pipeline, and procurement/security teams writing tests. Start with RAG + connector “preview” mode and add targeted fine-tuning only where deterministic outputs are business-critical. And build your observability early—when your AI does something wrong, you want to know why before your customer does.